
This document walks the full workflow on simulated data, simulated HERE, in the vignette, so that every number shown has the truth sitting next to it. An example whose result cannot be checked teaches nothing.
1. Simulate a herd
A pedigree with herd structure (few sires, many dams) and genetic
values by the recursion
a = 0.5(a_sire + a_dam) + mendelian, never by a Cholesky of
A, which would share code with the very thing we are testing.
library(BreedingR)

n <- 800
id <- sprintf("a%04d", 1:n)
sire <- dam <- rep("0", n)
for (i in 61:n) {
  sire[i] <- id[sample(1:20, 1)]
  dam[i] <- id[sample(1:(i - 1), 1)]
}
ped <- data.frame(id, sire, dam)

p <- pedigree(ped)   # topological order + Meuwissen-Luo (1992) inbreeding
p
#> Pedigree with 800 animals, 60 founder(s)
#> Mean F 0.022051, maximum 0.5, 89 animal(s) with F > 0
#>      id sire dam F
#> 1 a0001   NA  NA 0
#> 2 a0002   NA  NA 0
#> 3 a0003   NA  NA 0
#> 4 a0004   NA  NA 0
#> 5 a0005   NA  NA 0
#> ... and 795 more row(s)
va <- 0.4; ve <- 0.6           # the truth: h2 = 0.4
a <- numeric(n)
for (i in 1:n) {
  s <- p$sire[i]; d <- p$dam[i]
  mend <- if (!is.na(s) && !is.na(d)) 0.5 - 0.25 * (p$F[s] + p$F[d])
          else if (!is.na(s) || !is.na(d)) 0.75 else 1
  base <- 0
  if (!is.na(s)) base <- base + 0.5 * a[s]
  if (!is.na(d)) base <- base + 0.5 * a[d]
  a[i] <- base + sqrt(mend * va) * rnorm(1)
}
cg <- sample(sprintf("g%02d", 1:10), n, replace = TRUE)
efc <- setNames(rnorm(10), sprintf("g%02d", 1:10))
data <- data.frame(id = p$id, cg = cg,
                    peso = 30 + efc[cg] + a + sqrt(ve) * rnorm(n))
2. Look before estimating
describe(data, "peso", classes = "cg", pedigree = ped)
#> Trait 'peso': 800 record(s)
#>   mean 29.937, sd 1.2304
#>   quartiles 25.42 / 29.16 / 29.98 / 30.77 / 33.15
#>   6 record(s) outside the Tukey fences [26.75, 33.17]
#>   class cg: 10 level(s), smallest 62, median 77, 0 with a single record
#>   pedigree: 800 animals, 60 founder(s), mean F 0.02205, maximum 0.5
3. Fit the animal model
fit <- model(peso ~ cg + animal(id), data, pedigree = ped)
fit
#> AI-REML fit of 'peso'
#>   converged in 11 iteration(s), relDelta 2.48e-09, Newton decrement 1.77e-17, 0.009 s
#>   -2logL 721.7153246
#>   800 record(s), 810 column(s) in the equations
#>   fixed column(s) removed for linear dependence: cg=g10
#>
#>      component estimate std_error  share correlation
#>    var(animal) 0.400408 0.0805395 0.4044
#>  var(residual) 0.589626 0.0545863 0.5956
#>
#> fixed effects (implicit intercept; dropped columns are zero; compare by contrast):
#>  intercept     cg=g06     cg=g05     cg=g03     cg=g04     cg=g01     cg=g07
#> 30.4257952 -1.5842893 -1.6815266 -1.2334479  0.3043911  0.1306684 -0.9679225
#>     cg=g08     cg=g09     cg=g02
#> -0.0685500  0.0851763 -0.3198298
The truth was va = 0.4, ve = 0.6. The
distance in standard errors is what says whether the recovery is within
expectation; an estimator that hit 0.400 on the nose would be reading
the answer, not estimating it.
h2() takes the numerator by name and divides by the
phenotypic variance, covariances included (a direct-maternal covariance
belongs there), never the rho of an AR(1) residual:
4. Breeding values and accuracy
vg <- ebv(fit)
acc <- accuracy(fit, ped)
summary(acc)
#>    Min. 1st Qu.  Median    Mean 3rd Qu.    Max.
#>  0.6287  0.7275  0.7431  0.7498  0.7625  0.9301
head(solutions(fit, ped), 5)     # the same numbers as one table, sorted by EBV
#>        id      ebv        se       acc
#> 602 a0602 1.466847 0.4276190 0.7966533
#> 755 a0755 1.455246 0.4341365 0.7626233
#> 367 a0367 1.407798 0.4099199 0.7618019
#> 711 a0711 1.386555 0.4401518 0.7828968
#> 197 a0197 1.321966 0.4033244 0.8215778
plot(vg[order(vg)], acc[order(vg)], pch = ".", cex = 2,
     xlab = "EBV (sorted)", ylab = "accuracy")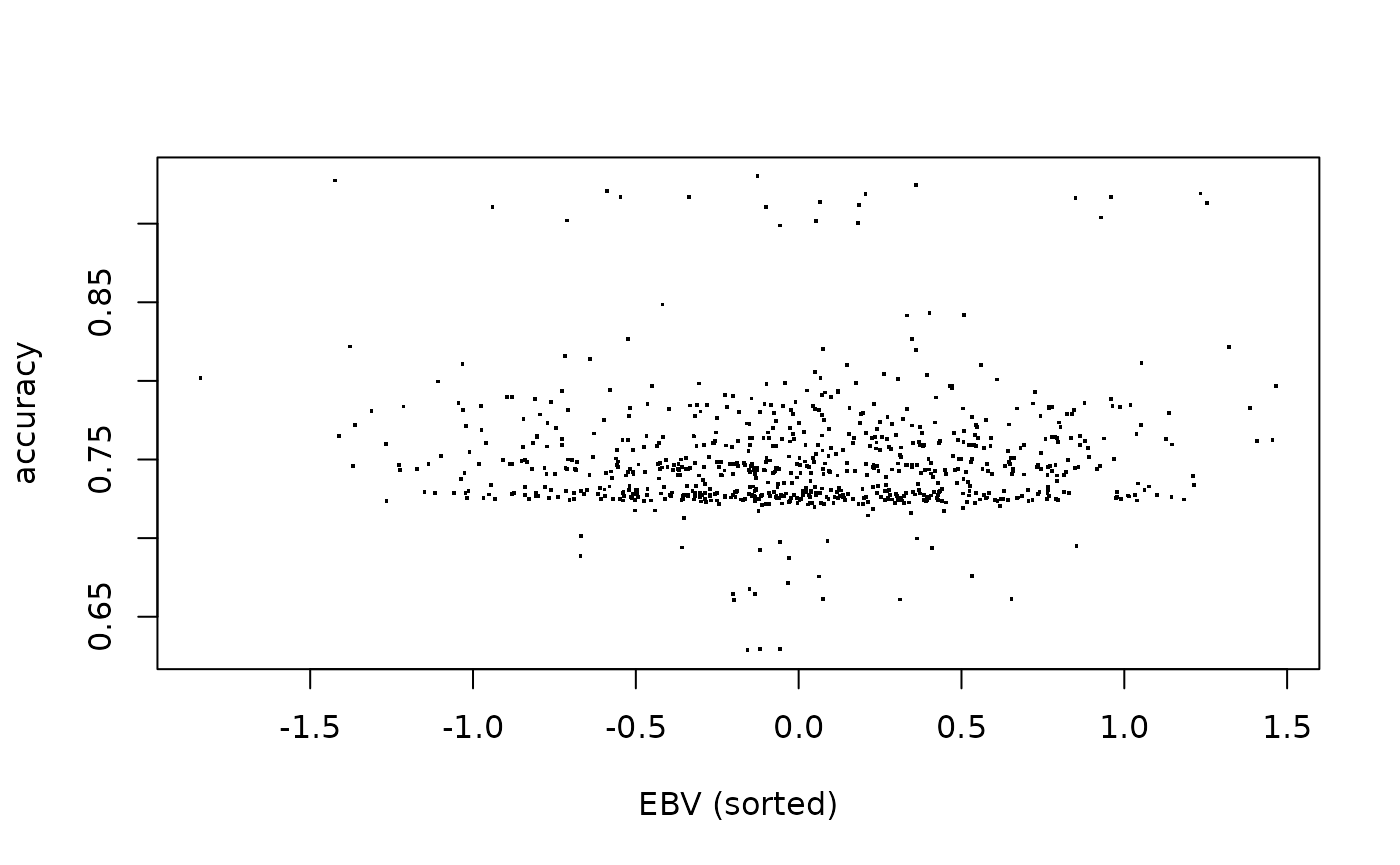
5. Models the formula declares without a dedicated fitter
The layout unit is the covariance group: group = "g"
puts two random terms into the same matrix, with the correlation
estimated.
These calls need columns the herd above does not have: the dam of
each record, an age idade, a pen baia, and a
0/1/2 genotype matrix M with its ids gids.
With them:
# direct-maternal
model(peso ~ cg + animal(id, group = "g") + maternal(dam, group = "g"), data, ped)

# reaction norm on a Legendre basis; pe(id) needs repeated records per animal
d2 <- cbind(data, legendre(data$idade, order = 1, limits = c(150, 190)))
model(peso ~ cg + rn(id, base = c("phi0", "phi1")) + pe(id), d2, ped)

# indirect genetic effect (the associative model of Muir & Schinckel, 2002);
# h2(fit, n = ) and t2(fit, n = ) read it with the pen size
model(peso ~ cg + animal(id, group = "g") + indirect(id, pen = "baia", group = "g"),
        data, ped)

# single step, with the 0/1/2 genotype matrix
model(peso ~ cg + animal(id), data, ped, genotypes = list(ids = gids, m = M))
6. The Bayesian half
The same model, sampled instead of maximized. The posterior means should land near the REML estimates, and they carry the whole distribution with them.
gb <- gibbs(peso ~ cg + animal(id), data, pedigree = ped,
            n_iter = 3000, burnin = 500, thin = 5)
data.frame(component = colnames(gb$samples),
           posterior = round(unname(gb$mean), 3),
           reml = round(unname(fit$theta), 3))
#>       component posterior reml
#> 1   var(animal)     0.397 0.40
#> 2 var(residual)     0.597 0.59
7. Genomics without ever building G
For genomic examples the package ships its own generator,
simulate_breeding(), which gene-drops haplotypes so the
genotypes are CONSISTENT with the pedigree it emits. The single step
runs three ways: exact, apy_core= (a global core, or
"auto" to size it by the eigenvalues of G), or
vecchia_k= (each animal conditions on its own k strongest
previous relationships; Henderson’s (1976) A^-1 is this recursion with
the parents as the set). And snp_blup() drops G entirely:
markers enter as equations and the system is solved by conjugate
gradients at given components.
s <- simulate_breeding(n_founders = 40, n_generations = 2,
                       offspring_per_generation = 80, h2 = 0.4,
                       n_markers = 300, seed = 7)
fg <- model(y ~ cg + animal(id), s$data, s$pedigree, genotypes = s$genotypes)
fs <- snp_blup(y ~ cg + animal(id), s$data, s$pedigree, s$genotypes,
               theta = unname(fg$theta))
cor(ebv(fg, "animal"), ebv(fs, "animal")[names(ebv(fg, "animal"))])
#> [1] 0.9999969
The two paths differ by a declared detail (the affine adjustment of
G* that snp_blup() does not apply), so the correlation is
near 1 without being 1. PLINK files enter through
read_plink(), and qc_genotypes() filters call
rate, MAF and HWE while REPORTING what each filter removed.
8. The selection side
tbv <- s$tbv[names(ebv(fg, "animal"))]
idx <- selection_index(list(y = ebv(fg, "animal")), c(y = 1))
dr <- rank_drift(ebv(fs, "animal"), ebv(fg, "animal"), top = 50)
c(cor_index_tbv = round(cor(idx[names(tbv)], tbv), 2),
  drift_spearman = round(dr$spearman, 4), retention_50 = dr$retention)
#>  cor_index_tbv drift_spearman   retention_50
#>           0.67           1.00          50.00
mc_study() repeats simulate-and-refit so a recovery
claim has a bias and a spread instead of one lucky seed;
suggest_model() reads the shape of the data and names the
term each shape asks for; benchmark_fit() refuses to time
anything fewer than three times.
9. What the package does NOT do silently
These choices live in the errors, on purpose:
- a parent that is cited but has no line of its own is an ERROR, not a founder;
- a genotype outside 0, 1, 2 and NA is refused (NA is imputed to the mean; zero is a valid genotype and is never used as a missing-value code);
- an animal not in the pedigree (a pen mate too) enters as a FOUNDER with a warning that names it, never as a silent discard; an id written differently from its pedigree line is an ERROR with both spellings;
- an INADMISSIBLE theta halts the fit, it never turns into a result;
- a fit that did not converge SAYS so in the print, in the message and in the object.